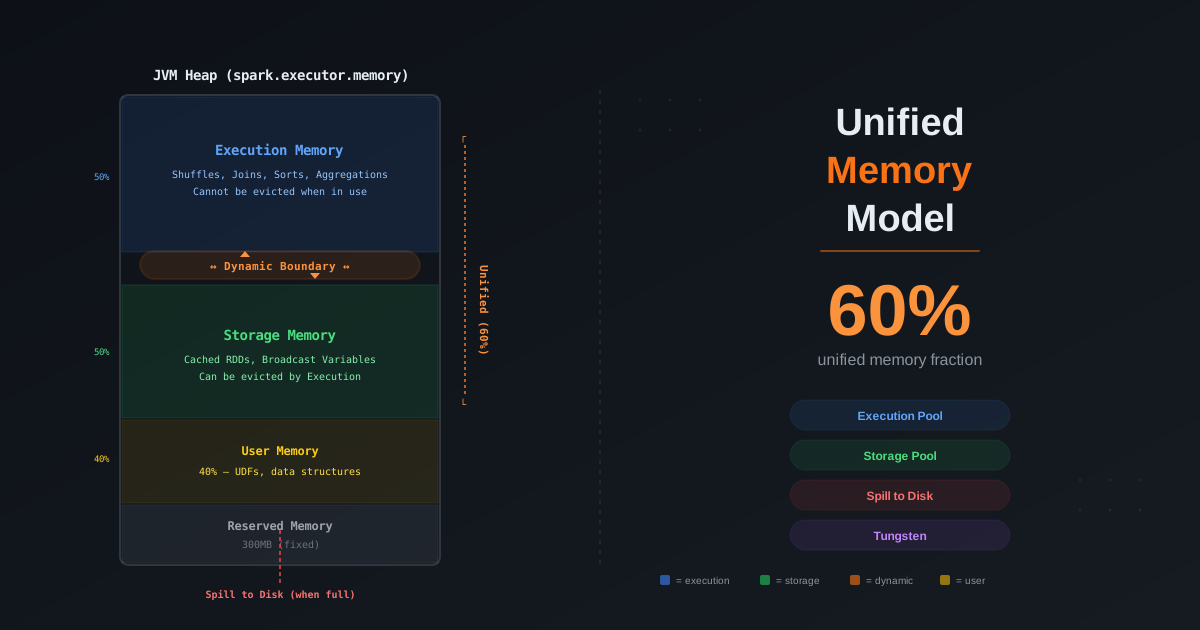
Spark Memory Architecture: The Complete Guide to the Unified Memory Model
A deep dive into Apache Spark's unified memory model — how execution and storage memory share the JVM heap, exact formulas for every memory region, driver vs executor memory layout, off-heap memory with Tungsten, container memory formulas for YARN and Kubernetes, PySpark memory architecture, and how to right-size your Spark clusters.
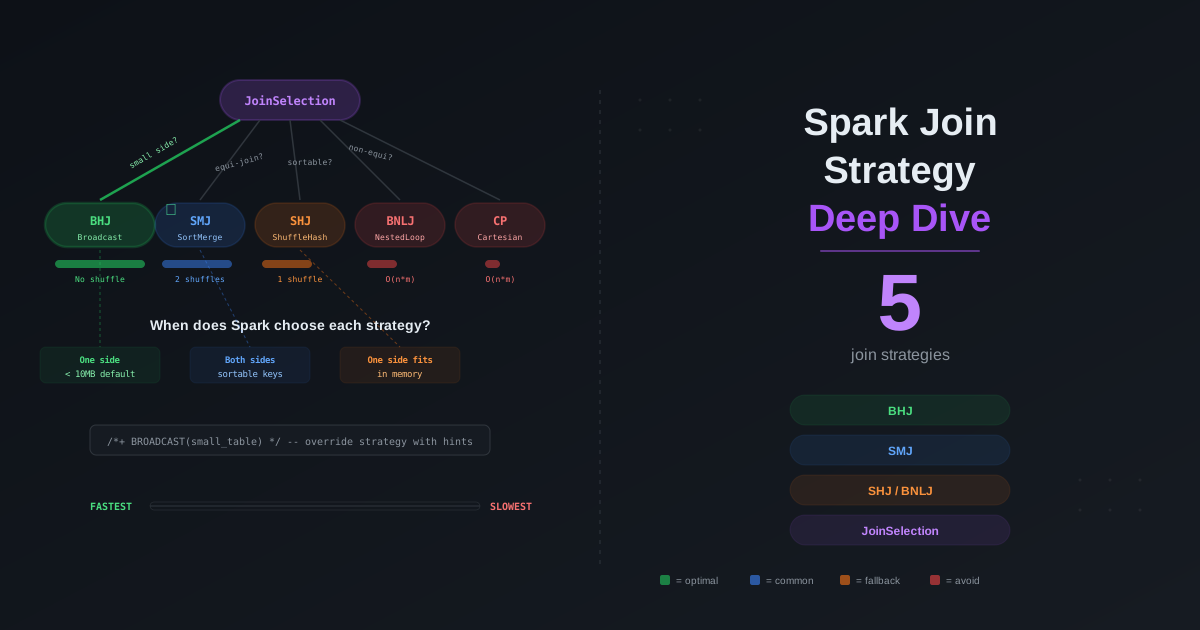
Spark SQL Join Strategy: The Complete Optimization Guide
A comprehensive deep dive into every Apache Spark join strategy — BroadcastHashJoin, SortMergeJoin, ShuffledHashJoin, BroadcastNestedLoopJoin, CartesianProduct — how JoinSelection picks one, the Catalyst optimizer's size estimation, CBO join reordering, all join hints, AQE runtime optimization, equi vs non-equi joins, physical plan reading, common anti-patterns, and a real-world decision framework for Iceberg and Cazpian.
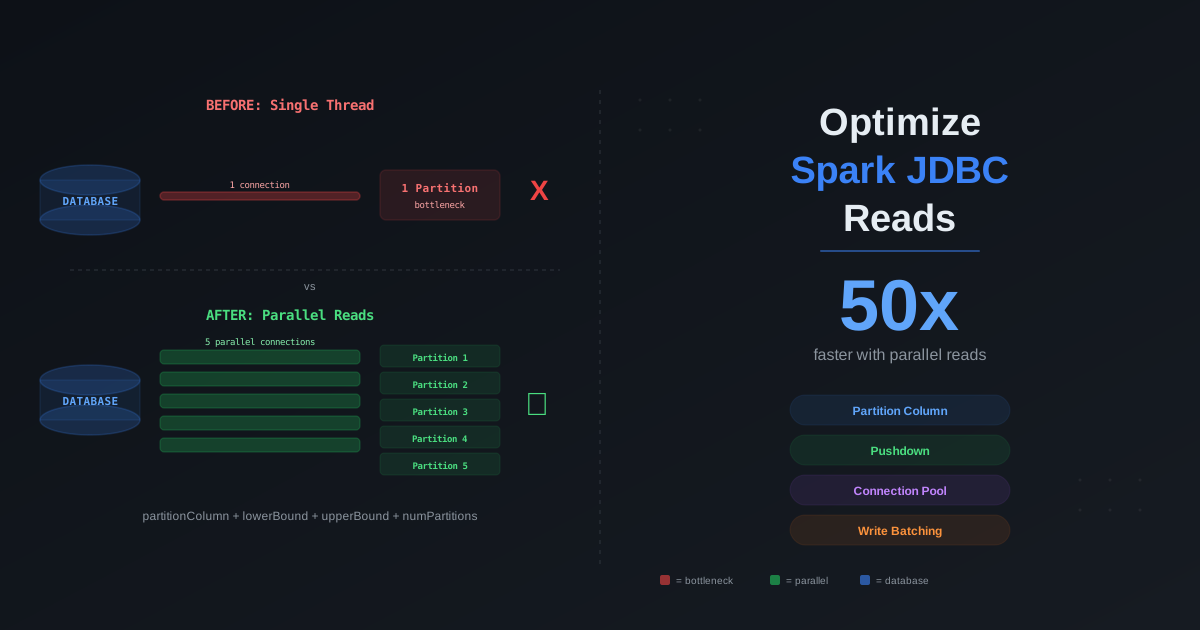
Spark JDBC Data Source: The Complete Optimization Guide for Reads, Writes, and Pushdown
A comprehensive deep dive into Apache Spark JDBC data source optimizations — the single-thread default problem, parallel reads with partitionColumn/numPartitions, custom predicates for non-numeric columns, all pushdown optimizations (predicate, aggregate, limit, sort, join), fetchSize and batchSize tuning, database-specific optimizations for PostgreSQL/MySQL/Oracle/SQL Server, writing optimizations, connection pooling, advanced patterns with subqueries and Iceberg ingestion, monitoring and debugging JDBC reads, anti-patterns, and a complete configuration reference with defaults and recommended values.
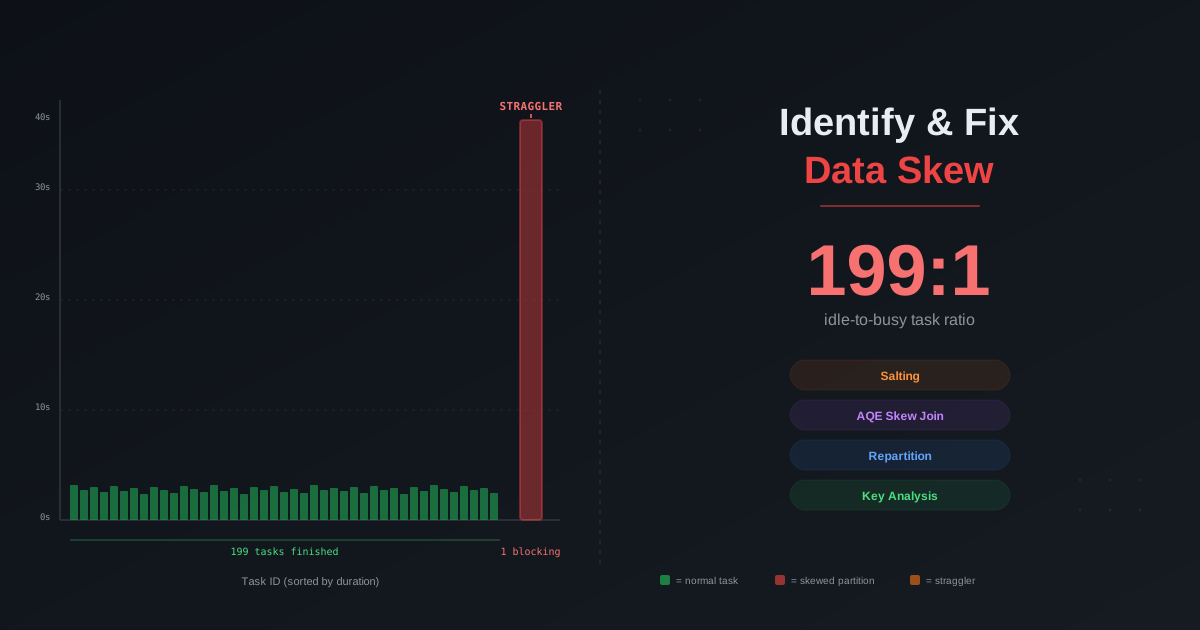
Spark Data Skew: The Complete Guide to Identification, Debugging, and Optimization
A deep dive into Apache Spark data skew — what it is, why it kills performance, how to identify it in the Spark UI, all types of skew (join, aggregation, null key, time-based, write), AQE skew join and coalesce optimizations with every config, manual fixes including salting with code examples, two-phase aggregation, isolate-and-broadcast, Iceberg partition and file skew detection and compaction fixes, anti-patterns, and a complete configuration reference.
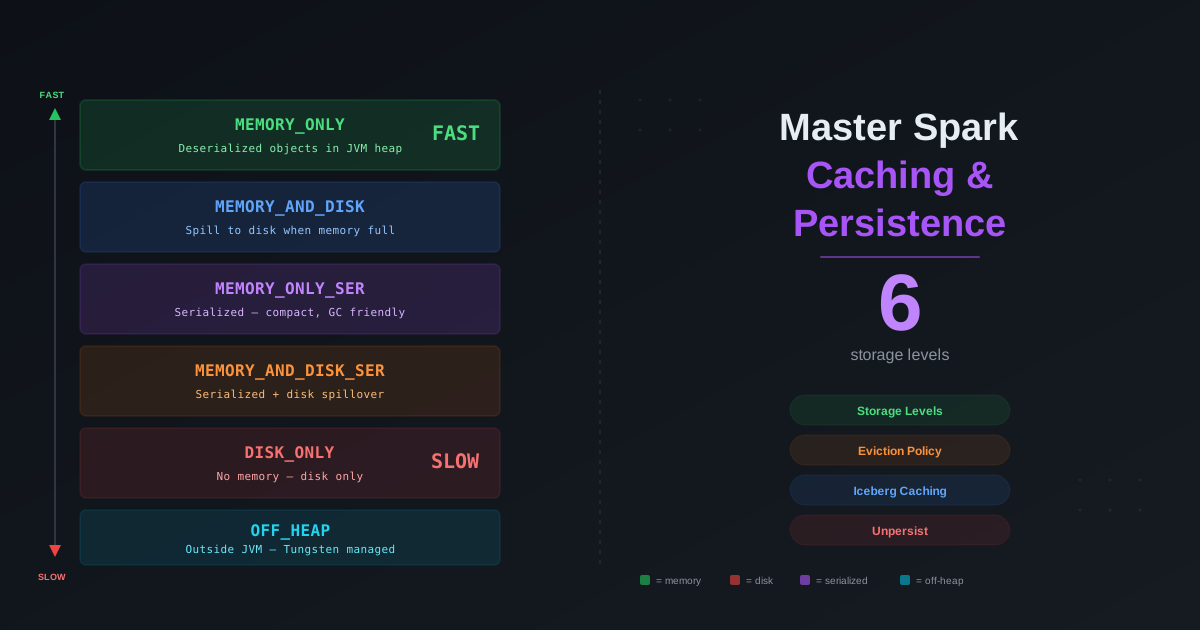
Spark Caching and Persistence: The Complete Guide for Iceberg and Cazpian
A deep dive into Apache Spark caching — how it works internally, all storage levels, every way to cache, how caching converts Sort-Merge to Broadcast joins, in-memory columnar storage, memory management, recommended cache sizes, Spark UI Storage tab diagnostics, Iceberg-specific caching behavior, and real-world optimization patterns.
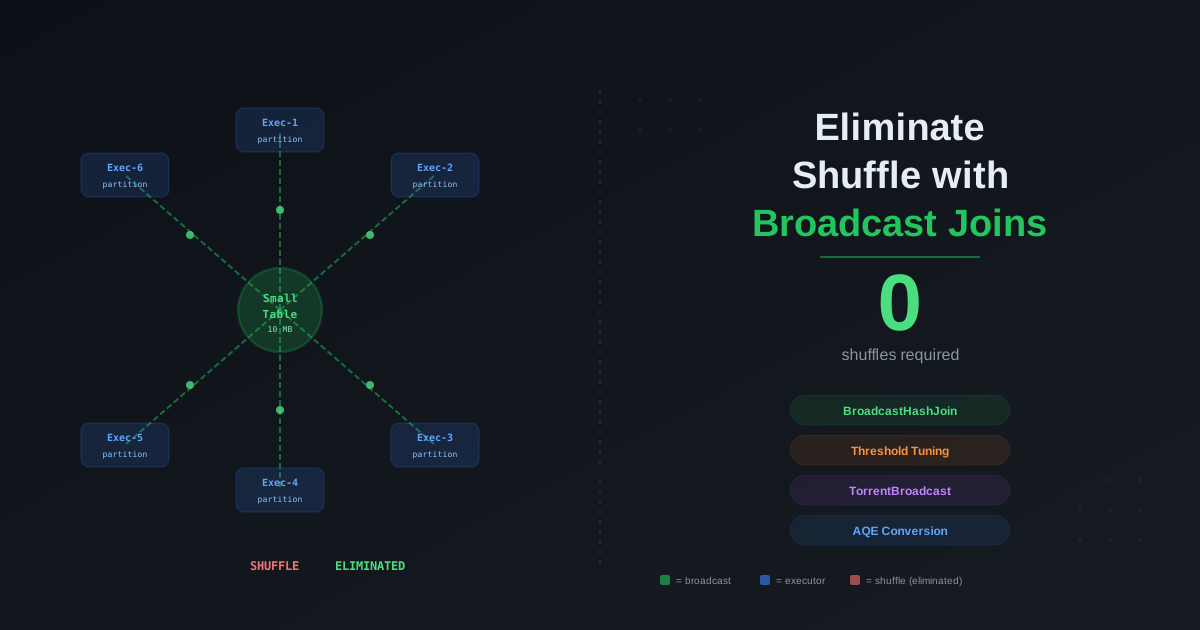
Spark Broadcast Joins: The Complete Guide for Iceberg and Cazpian
A deep dive into Apache Spark broadcast joins — how they work internally, all five ways to trigger them, AQE adaptive broadcast, driver memory math, real-world optimization patterns, downsides, configuration reference, and how Cazpian compute pools leverage broadcast for faster Iceberg queries.
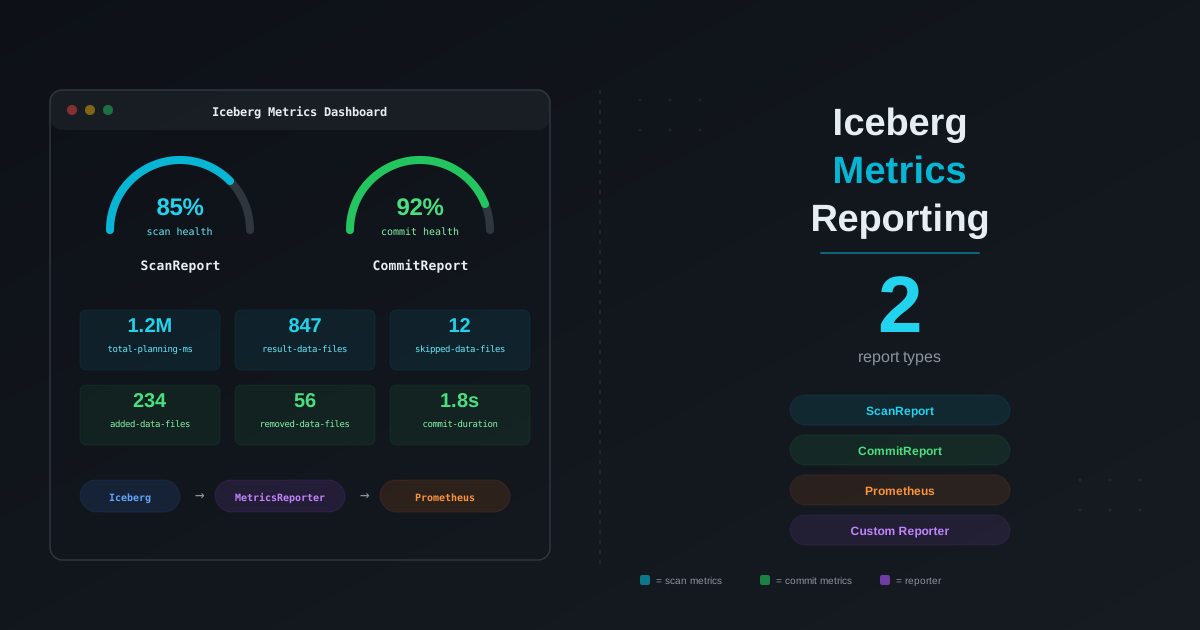
Iceberg Metrics Reporting: How to Monitor Scan and Commit Health with Spark
A complete guide to monitoring Apache Iceberg table health — from ScanReport and CommitReport metrics to metadata table queries, snapshot summary trends, column-level clustering analysis, and Puffin file statistics. Learn to diagnose slow scans, commit contention, delete file overhead, small file problems, and turn metrics into maintenance actions.
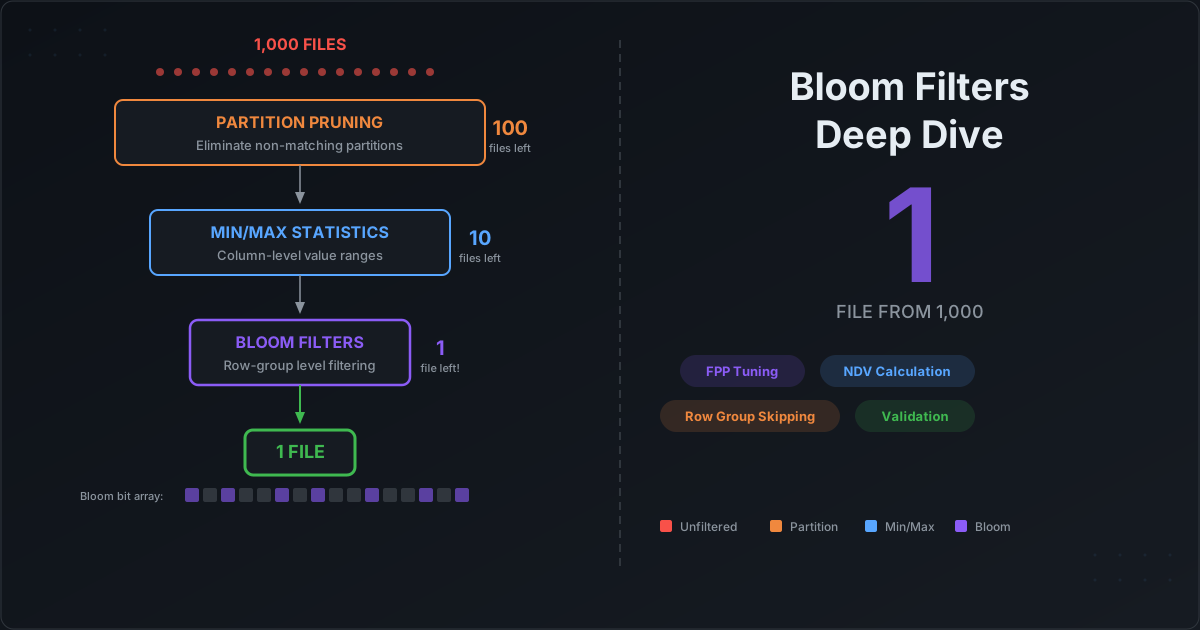
Iceberg Bloom Filters with Spark: Configuration, Validation, and Performance Guide
A complete guide to Parquet bloom filters on Apache Iceberg tables — how they work internally, when to use them, how to configure per-column bloom filters, how to validate they exist in Parquet files, false positive behavior, performance benchmarks, and production best practices.
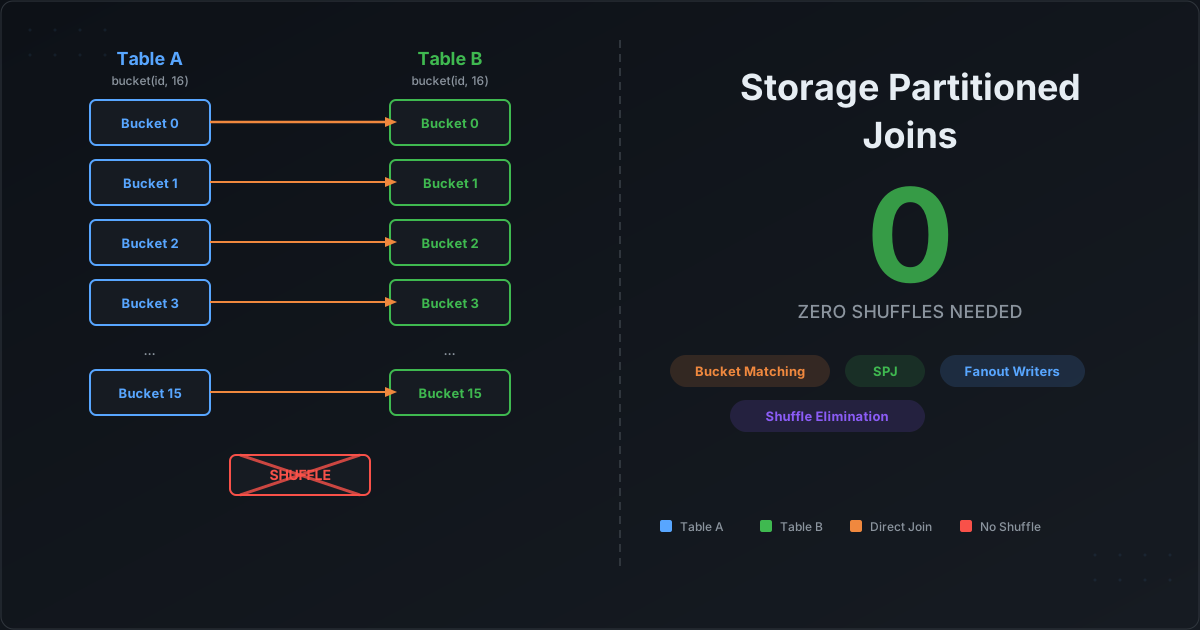
Storage Partitioned Joins in Apache Iceberg with Spark
How Storage Partitioned Joins (SPJ) eliminate shuffle operations on Apache Iceberg tables — setup guide, Spark configuration, MERGE INTO optimization, physical plan verification, edge cases, and Spark 4.0 enhancements.
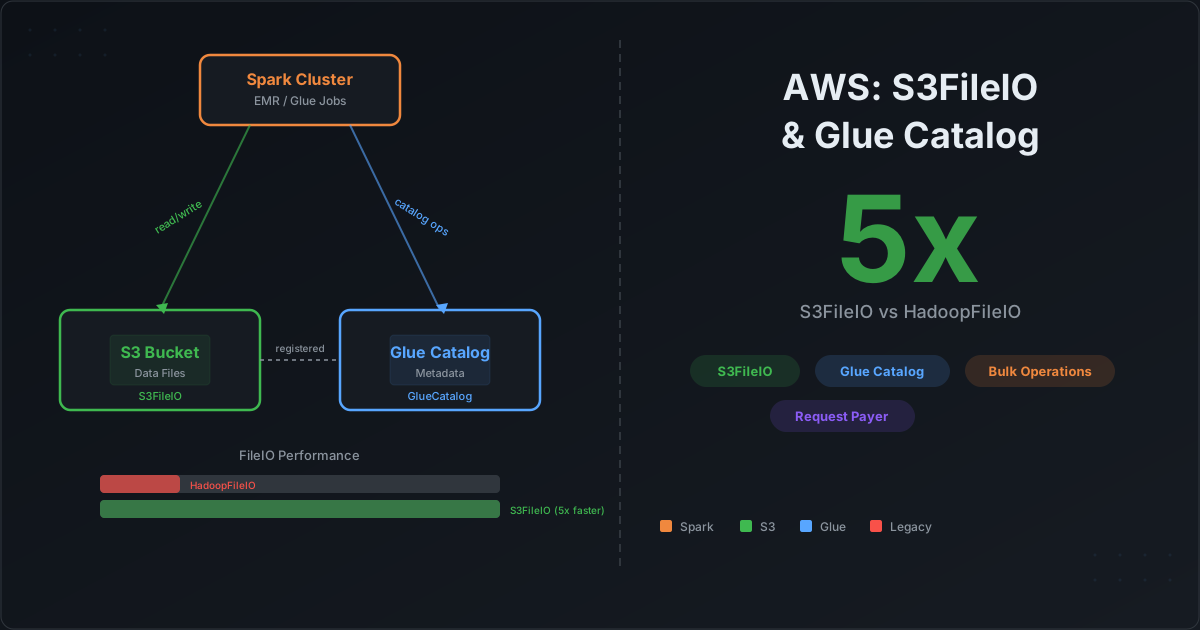
Iceberg on AWS: S3FileIO, Glue Catalog, and Performance Optimization Guide
A complete guide to running Apache Iceberg on AWS — why S3FileIO outperforms HadoopFileIO (s3a), how to configure progressive multipart uploads, ObjectStoreLocationProvider for S3 throttling avoidance, Glue catalog optimistic locking, server-side encryption, credential vending, and every S3FileIO property you need in production.
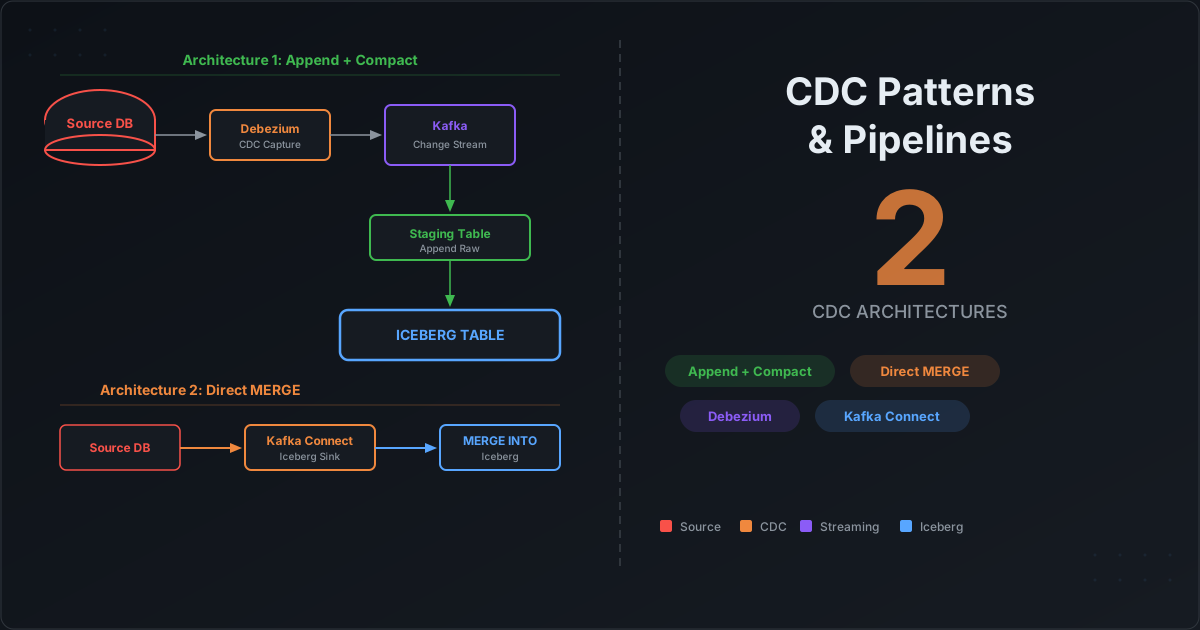
Iceberg CDC: Patterns, Best Practices, and Real-World Pipelines
A practical guide to building Change Data Capture pipelines on Apache Iceberg — covering direct CDC with Flink, the bronze-silver pattern with Spark MERGE INTO, Iceberg's create_changelog_view, CDC table design, compaction strategies, and production operational patterns.
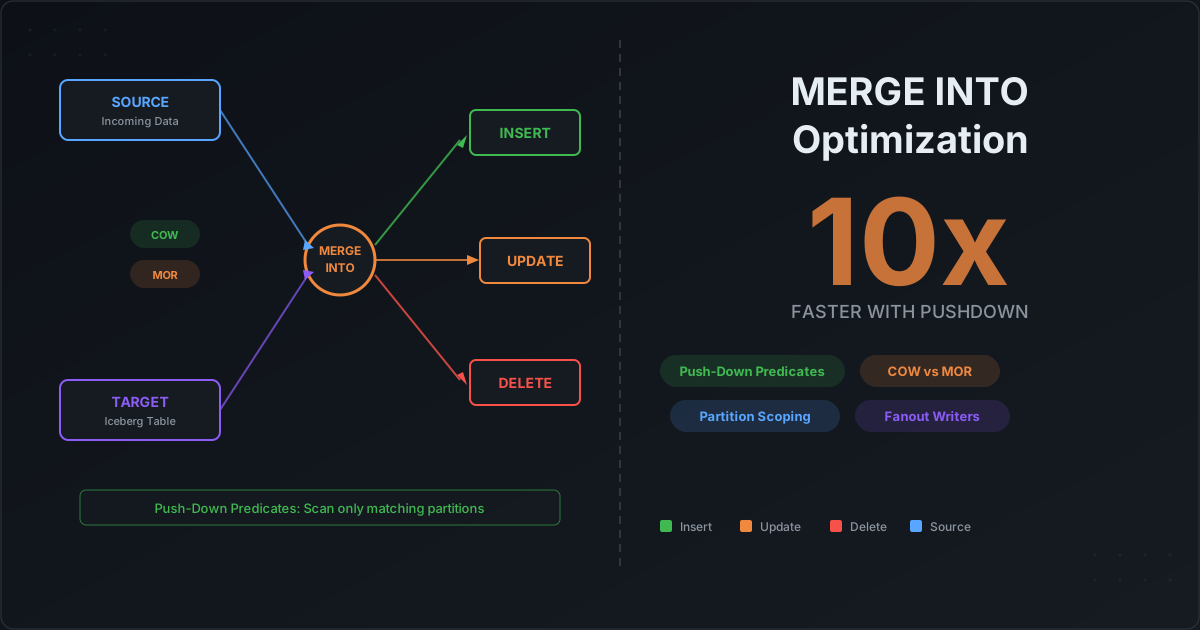
Writing Efficient MERGE INTO Queries on Iceberg with Spark
How to write fast, cost-efficient MERGE INTO queries on Apache Iceberg tables with Spark — covering push-down predicates, partition-scoped merges, COW vs MOR trade-offs, distribution mode impact, and compaction strategies after merges.